Cookbook
Cookbook.RmdLoad
suppressPackageStartupMessages(library(dplyr))
library(gsm.core)
library(gsm.mapping)
library(gsm.kri)
library(gsm.reporting)
library(gsm.studykri)
#>
#> Attaching package: 'gsm.studykri'
#> The following object is masked from 'package:gsm.reporting':
#>
#>     BindResults
Introduction
{gsm.studykir} presents an new approach for calculating KRI lower and upper limits on study-level for quality monitoring in clincial trials. The method uses bootstrapping to calculate confidence intervals gor a given study over-time. The confidence intervals can then be used to compare the study-level KRI against a fixed expectation or against the confidence intervalls and KRI values over time of one or more reference studies. The bootstrapping method resamples a new set of sites with replacement from the original study data set.
Simulate Data Set
We use the clindata package which includes data from one clinical study to simulate new study data. We create a portfolio with study AA-4 oversampling patients with low AE counts.
lRaw <- list(
  Raw_SITE = clindata::ctms_site,
  Raw_STUDY = clindata::ctms_study,
  Raw_PD = clindata::ctms_protdev,
  Raw_DATAENT = clindata::edc_data_pages,
  Raw_QUERY = clindata::edc_queries,
  Raw_AE = clindata::rawplus_ae,
  Raw_SUBJ = clindata::rawplus_dm,
  Raw_ENROLL = clindata::rawplus_enroll,
  Raw_Randomization = clindata::rawplus_ixrsrand,
  Raw_LB = clindata::rawplus_lb,
  Raw_SDRGCOMP = clindata::rawplus_sdrgcomp,
  Raw_STUDCOMP = clindata::rawplus_studcomp,
  Raw_VISIT = clindata::rawplus_visdt
)

# to ensure proper resampling we need to make sure that lRaw$Raw_SUBJ
# can be used as a proper lookup table for all subject identifier aliases

lRaw$Raw_SUBJ$subjectname <- lRaw$Raw_SUBJ$subject_nsv
lRaw$Raw_SUBJ$subjectenrollmentnumber <- lRaw$Raw_SUBJ$subjectid

lPortfolio <- SimulatePortfolio(
  lRaw = lRaw,
  nStudies = 4,
  vSubjectIDs = c("subjid", "subjectenrollmentnumber", "subject_nsv", "subjectname", "subjectid"),
  dfConfig = tibble(
    studyid = c("AA-1", "AA-2", "AA-3", "AA-4"),
    nSubjects = c(500, 750, 150, 200),
    strOversampleDomain = rep("Raw_AE", 4),
    vOversamplQuantileRange_min = c(0, 0, 0, 0),
    vOversamplQuantileRange_max = c(0.5, 1, 1, 1)
  )
)
#> Filtered to 521 subjects with Raw_AE records in 0.00-0.50 quantile range (1-3 records)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
Calculate KRI
We will calculate the KRI “AE per visit”. For this we need to create three dataframes:
- dfSubjects: Subject-level data that links subjects and sites from the demographics domain
- dfNumerator: Subject-level data that contains the events to be counted (AEs in this case)
- dfDenominator: Subject-level data that contains the denominator events (visits in this case
that we transform to return the site-level count of numerator and denominator per month
dfInput <- gsm.studykri::Input_CountSiteByMonth(
  dfSubjects = lPortfolio$Raw_SUBJ,
  dfNumerator = lPortfolio$Raw_AE,
  dfDenominator = lPortfolio$Raw_VISIT %>%
    mutate(visit_dt = as.Date(visit_dt)),
  strStudyCol = "studyid",
  strGroupCol = "invid",
  strGroupLevel = "Site",
  strSubjectCol = "subjid",
  strNumeratorDateCol = "aest_dt",
  strDenominatorDateCol = "visit_dt",
  nMinDenominator = 25 # Normalize dates at the threshold
)

dfInput
#> # A tibble: 18,252 × 7
#>    GroupID    GroupLevel Numerator Denominator Metric StudyID MonthYYYYMM
#>    <chr>      <chr>          <int>       <int>  <dbl> <chr>         <dbl>
#>  1 AA-1_0X004 Site               1           1  1     AA-1         201105
#>  2 AA-1_0X005 Site               1           1  1     AA-1         200811
#>  3 AA-1_0X005 Site               1           0 NA     AA-1         200906
#>  4 AA-1_0X005 Site               1           1  1     AA-1         201105
#>  5 AA-1_0X005 Site               1           1  1     AA-1         201204
#>  6 AA-1_0X011 Site               1           1  1     AA-1         200411
#>  7 AA-1_0X011 Site               1           1  1     AA-1         201107
#>  8 AA-1_0X011 Site               2           3  0.667 AA-1         201306
#>  9 AA-1_0X011 Site               1           0 NA     AA-1         201506
#> 10 AA-1_0X011 Site               1           2  0.5   AA-1         201601
#> # ℹ 18,242 more rows
Alternatively we can also use days on study as a denominator by passing subjects as denominator and an end date.
dfInputDays <- gsm.studykri::Input_CountSiteByMonth(
  dfSubjects = lPortfolio$Raw_SUBJ,
  dfNumerator = lPortfolio$Raw_AE,
  dfDenominator = lPortfolio$Raw_SUBJ,
  strStudyCol = "studyid",
  strGroupCol = "invid",
  strGroupLevel = "Site",
  strSubjectCol = "subjid",
  strNumeratorDateCol = "aest_dt",
  strDenominatorDateCol = "firstparticipantdate",
  strDenominatorEndDateCol = "lastparticipantdate",
  nMinDenominator = 25 # Normalize dates at the threshold
)

dfInputDays
#> # A tibble: 22,473 × 7
#>    GroupID    GroupLevel Numerator Denominator Metric StudyID MonthYYYYMM
#>    <chr>      <chr>          <int>       <int>  <dbl> <chr>         <dbl>
#>  1 AA-1_0X004 Site               1          31 0.0323 AA-1         201105
#>  2 AA-1_0X005 Site               1          30 0.0333 AA-1         200811
#>  3 AA-1_0X005 Site               1          30 0.0333 AA-1         200906
#>  4 AA-1_0X005 Site               1          31 0.0323 AA-1         201105
#>  5 AA-1_0X005 Site               1          30 0.0333 AA-1         201204
#>  6 AA-1_0X011 Site               1          30 0.0333 AA-1         200411
#>  7 AA-1_0X011 Site               1          31 0.0323 AA-1         201107
#>  8 AA-1_0X011 Site               2          53 0.0377 AA-1         201306
#>  9 AA-1_0X011 Site               1          30 0.0333 AA-1         201506
#> 10 AA-1_0X011 Site               1          31 0.0323 AA-1         201601
#> # ℹ 22,463 more rows
Next we transform the data to return the cumulated event counts on study-level by study month. Date normalization is now done at the input level, so Transform_CumCount performs pure aggregation.
dfTransformed <- gsm.studykri::Transform_CumCount(
  dfInput,
  vBy = c("StudyID")
)

dfTransformed
#> # A tibble: 745 × 7
#>    StudyID MonthYYYYMM StudyMonth Numerator Denominator Metric GroupCount
#>    <chr>         <dbl>      <int>     <int>       <int>  <dbl>      <int>
#>  1 AA-1         200404          1         6          28 0.214           9
#>  2 AA-1         200405          2         8          45 0.178          12
#>  3 AA-1         200406          3         8          61 0.131          13
#>  4 AA-1         200407          4        10          85 0.118          16
#>  5 AA-1         200408          5        12         115 0.104          18
#>  6 AA-1         200409          6        17         142 0.120          17
#>  7 AA-1         200410          7        18         176 0.102          19
#>  8 AA-1         200411          8        20         208 0.0962         19
#>  9 AA-1         200412          9        23         238 0.0966         18
#> 10 AA-1         200501         10        26         276 0.0942         21
#> # ℹ 735 more rows
Analyze_StudyKRI_PredictBounds calculates upper and lower confidence intervals of the study metrics KRI using a bootstrap technique.
dfBounds <- dfInput %>%
  gsm.studykri::Analyze_StudyKRI_PredictBounds()
#> Using all 4 studies found in dfInput

dfBounds
#> # A tibble: 745 × 6
#>    StudyID StudyMonth Median  Lower Upper BootstrapCount
#>    <chr>        <int>  <dbl>  <dbl> <dbl>          <int>
#>  1 AA-1             1 0.214  0.0713 0.333           1000
#>  2 AA-1             2 0.172  0.0476 0.322           1000
#>  3 AA-1             3 0.127  0.0345 0.237           1000
#>  4 AA-1             4 0.115  0.0357 0.197           1000
#>  5 AA-1             5 0.104  0.0404 0.164           1000
#>  6 AA-1             6 0.120  0.0642 0.175           1000
#>  7 AA-1             7 0.102  0.0597 0.147           1000
#>  8 AA-1             8 0.0952 0.0621 0.134           1000
#>  9 AA-1             9 0.0973 0.0574 0.130           1000
#> 10 AA-1            10 0.0945 0.0613 0.124           1000
#> # ℹ 735 more rows
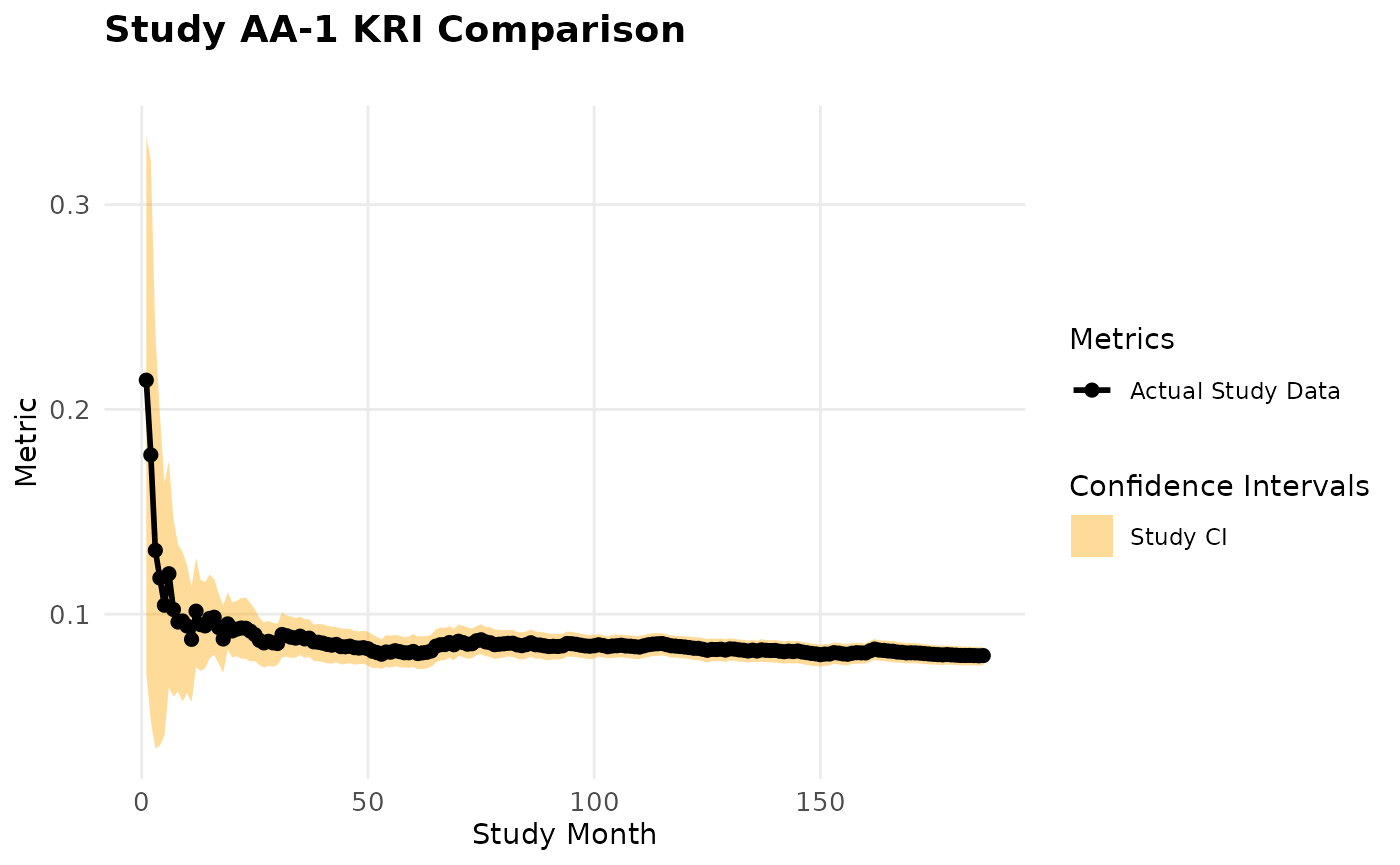
We can plot the preliminary results.
gsm.studykri::Visualize_StudyKRI(
  dfStudyKRI = dfTransformed,
  dfBounds = dfBounds,
  strStudyID = "AA-1"
)
We then calculate a reference confidence interval based on a set of reference studies.
dfStudyRef <- tibble(
  study = "AA-1",
  studyref = c("AA-2", "AA-3", "AA-4")
)

dfBoundsRef <- gsm.studykri::Analyze_StudyKRI_PredictBoundsRef(dfInput, dfStudyRef)
#> Calculated minimum group count: 74

dfBoundsRef
#> # A tibble: 187 × 9
#>    StudyMonth Median  Lower Upper BootstrapCount GroupCount StudyCount StudyID
#>         <int>  <dbl>  <dbl> <dbl>          <int>      <int>      <int> <chr>
#>  1          1  0.154 0      0.722           1000         74          3 AA-1
#>  2          2  0.143 0      0.519           1000         74          3 AA-1
#>  3          3  0.143 0      0.6             1000         74          3 AA-1
#>  4          4  0.120 0      0.654           1000         74          3 AA-1
#>  5          5  0.146 0.0294 0.651           1000         74          3 AA-1
#>  6          6  0.161 0.0526 0.663           1000         74          3 AA-1
#>  7          7  0.149 0.0476 0.607           1000         74          3 AA-1
#>  8          8  0.157 0.0541 0.611           1000         74          3 AA-1
#>  9          9  0.151 0.0571 0.577           1000         74          3 AA-1
#> 10         10  0.149 0.0575 0.527           1000         74          3 AA-1
#> # ℹ 177 more rows
#> # ℹ 1 more variable: StudyRefID <chr>
And add the reference confidence interval to our plot
gsm.studykri::Visualize_StudyKRI(
  dfStudyKRI = dfTransformed,
  dfBounds = dfBounds,
  dfBoundsRef = dfBoundsRef,
  strStudyID = "AA-1",
  bLogY = TRUE
)
#> Warning in ggplot2::scale_y_log10(): log-10 transformation
#> introduced infinite values.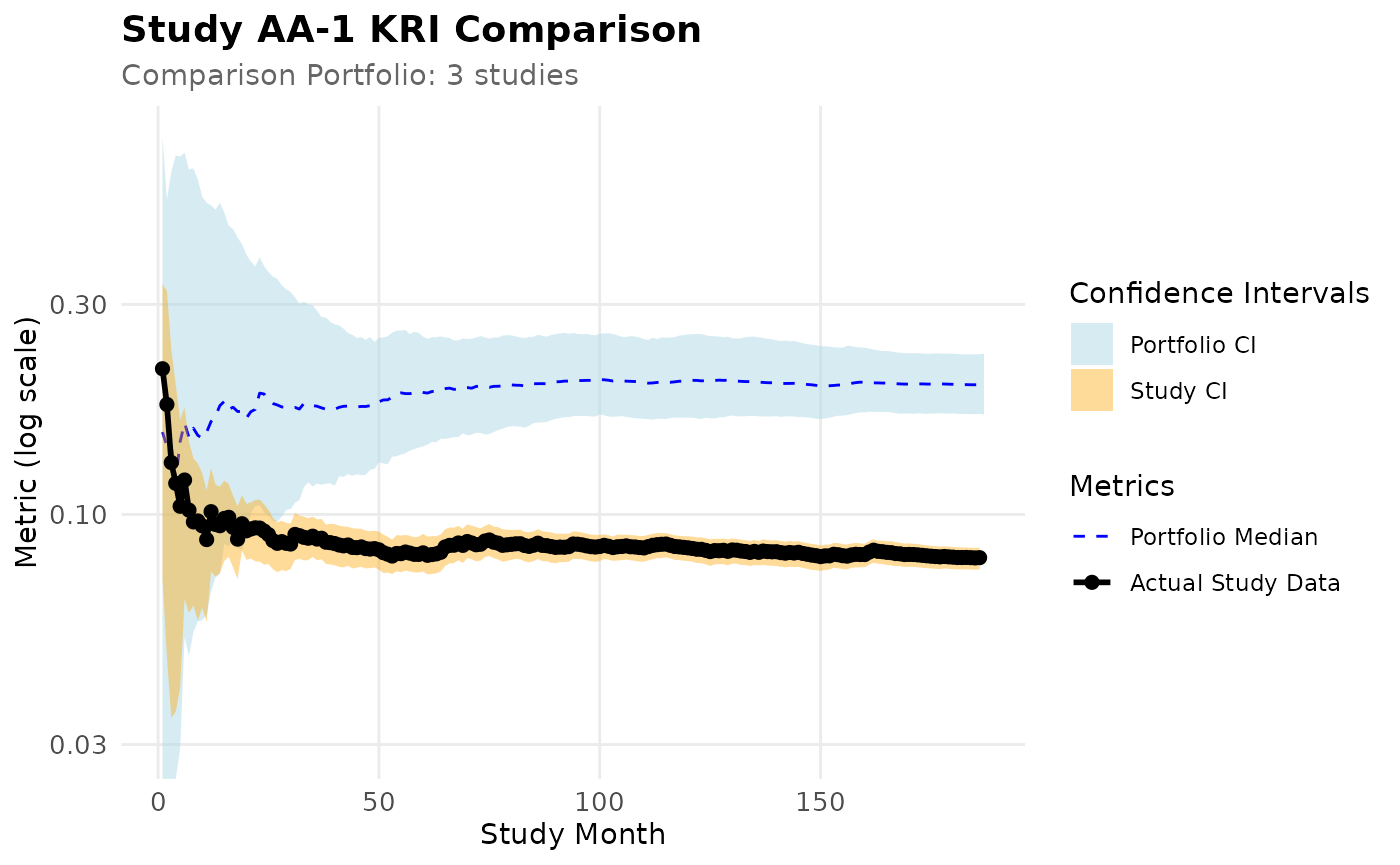
Bringing it together for Days on Study
dfTransformed <- gsm.studykri::Transform_CumCount(
  dfInputDays,
  vBy = c("StudyID")
)

dfBounds <- dfInputDays %>%
  gsm.studykri::Analyze_StudyKRI_PredictBounds()
#> Using all 4 studies found in dfInput

dfBoundsRef <- gsm.studykri::Analyze_StudyKRI_PredictBoundsRef(dfInputDays, dfStudyRef)
#> Calculated minimum group count: 74

library(ggplot2)

p <- gsm.studykri::Visualize_StudyKRI(
  dfStudyKRI = dfTransformed,
  dfBounds = dfBounds,
  dfBoundsRef = dfBoundsRef,
  strStudyID = "AA-1",
  bLogY = TRUE
)
Calculate KRI using yaml workflows
We can also use the {gsm}-style yaml workflow. Here we start with a portfolio with 6 studies of which 2 are target studies for whcih reports will be built, while the others serve as reference.
# Generate multi-study portfolio using SimulatePortfolio
lRaw_original <- list(
  Raw_SUBJ = clindata::rawplus_dm,
  Raw_AE = clindata::rawplus_ae,
  Raw_VISIT = clindata::rawplus_visdt,
  Raw_SITE = clindata::ctms_site,
  Raw_STUDY = clindata::ctms_study,
  Raw_PD = clindata::ctms_protdev,
  Raw_DATAENT = clindata::edc_data_pages,
  Raw_DATACHG = clindata::edc_data_points,
  Raw_QUERY = clindata::edc_queries,
  Raw_ENROLL = clindata::rawplus_enroll,
  Raw_Randomization = clindata::rawplus_ixrsrand,
  Raw_LB = clindata::rawplus_lb,
  Raw_SDRGCOMP = clindata::rawplus_sdrgcomp,
  Raw_STUDCOMP = clindata::rawplus_studcomp,
  Raw_IE = clindata::rawplus_ie
)

lRaw_original$Raw_SUBJ$subjectname <- lRaw_original$Raw_SUBJ$subject_nsv
lRaw_original$Raw_SUBJ$subjectenrollmentnumber <- lRaw_original$Raw_SUBJ$subjid

# Create a portfolio with 3 studies
lRaw <- SimulatePortfolio(
  lRaw = lRaw_original,
  nStudies = 3,
  seed = 123,
  vSubjectIDs = c("subjid", "subjectenrollmentnumber", "subject_nsv", "subjectname", "subjectid"),
  dfConfig = tibble(
    studyid = c("AA-1", "AA-2", "AA-3", "AA-4", "AA-5", "AA-6"),
    nSubjects = c(500, 750, 150, 200, 250, 300),
    strOversampleDomain = rep("Raw_AE", 6),
    vOversamplQuantileRange_min = c(0, 0, 0, 0, 0, 0),
    vOversamplQuantileRange_max = c(1, 0.75, 1, 1, 0.95, 0.9),
    nScreeningFailureRatio = c(0.2, 0.2, 0.2, 0.2, 0.2, 0.2)
  )
)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
#> Filtered to 773 subjects with Raw_AE records in 0.00-0.75 quantile range (1-6 records)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
#> Filtered to 1016 subjects with Raw_AE records in 0.00-1.00 quantile range (1-31 records)
#> Filtered to 969 subjects with Raw_AE records in 0.00-0.95 quantile range (1-13 records)
#> Filtered to 914 subjects with Raw_AE records in 0.00-0.90 quantile range (1-10 records)

lRaw$Raw_StudyRef <- tibble(
  studyid = c(rep("AA-1", 3), rep("AA-2", 4)),
  studyrefid = c("AA-3", "AA-4", "AA-5", "AA-3", "AA-4", "AA-5", "AA-6")
)

lRaw$Raw_ENROLL <- AddScreeningFailures(
  lRaw$Raw_ENROLL,
  lRaw_original$Raw_ENROLL,
  strSiteCol = "siteid",
  strStudyCol = "studyid"
)

# Run mapping workflows
mapping_wf <- gsm.core::MakeWorkflowList(
  strNames = NULL,
  strPath = system.file("workflow/1_mappings", package = "gsm.studykri"),
  strPackage = NULL
)

lIngest <- gsm.mapping::Ingest(lRaw, gsm.mapping::CombineSpecs(mapping_wf))
#> ℹ Ingesting data for AE.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 6545 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for ENROLL.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 3641 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for IE.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 38626 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for LB.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1457497 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for PD.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 5720 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for Randomization.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for SDRGCOMP.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 876 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for STUDCOMP.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 154 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for StudyRef.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 7 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for SUBJ.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for VISIT.
#> Creating a new temporary DuckDB connection.
#> Warning: Field `visit_dt`: 13 unparsable Date(s) set to NA
#> ✔ SQL Query complete: 36113 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for DATACHG.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 2719904 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for DATAENT.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 318256 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for SUBJ.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for IE.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 38626 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for ENROLL.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 3641 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for PD.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 5720 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for QUERY.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 54606 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for SITE.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 632 rows returned.
#> Disconnected from temporary DuckDB connection.
#> ℹ Ingesting data for STUDY.
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 6 rows returned.
#> Disconnected from temporary DuckDB connection.


lMapped <- gsm.core::RunWorkflows(lWorkflows = mapping_wf, lData = lIngest)
#>
#> ── Running 18 Workflows ────────────────────────────────────────────────────────
#>
#> ── Initializing `Mapped_AE` Workflow ───────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_AE
#> → All specified columns in Raw_AE are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Raw_AE$subjid, Raw_AE$aeser, Raw_AE$aest_dt, Raw_AE$aeen_dt, Raw_AE$mdrpt_nsv, Raw_AE$mdrsoc_nsv, Raw_AE$aetoxgr, Raw_AE$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_AE: No matching data found. Passing 'Mapped_AE' as a string.
#> ✔ rhs = Raw_AE: Passing lData$Raw_AE.
#>
#> ── Calling `=`
#>
#> ── 6545x8 data.frame saved as `lData$Mapped_AE`.
#>
#> ── Returning results from final step: 6545x8 data.frame`. ──
#>
#> ── Completed `Mapped_AE` Workflow ──────────────────────────────────────────────
#>
#> ── Initializing `Mapped_ENROLL` Workflow ───────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_ENROLL
#> → All specified columns in Raw_ENROLL are in the expected format
#> → All 7 specified column(s) in the spec are present in the data: Raw_ENROLL$studyid, Raw_ENROLL$invid, Raw_ENROLL$country, Raw_ENROLL$subjid, Raw_ENROLL$subjectid, Raw_ENROLL$enrollyn, Raw_ENROLL$enroll_dt
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_ENROLL: No matching data found. Passing 'Mapped_ENROLL' as a string.
#> ✔ rhs = Raw_ENROLL: Passing lData$Raw_ENROLL.
#>
#> ── Calling `=`
#>
#> ── 3641x7 data.frame saved as `lData$Mapped_ENROLL`.
#>
#> ── Returning results from final step: 3641x7 data.frame`. ──
#>
#> ── Completed `Mapped_ENROLL` Workflow ──────────────────────────────────────────
#>
#> ── Initializing `Mapped_IE` Workflow ───────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_IE
#> → All specified columns in Raw_IE are in the expected format
#> → All 5 specified column(s) in the spec are present in the data: Raw_IE$studyid, Raw_IE$subjid, Raw_IE$tiver, Raw_IE$ieorres, Raw_IE$iecat
#>
#> ── Workflow Step 1 of 2: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_IE: Passing lData$Raw_IE.
#> ℹ strQuery = SELECT * , CASE WHEN iecat = 'EXCL' AND ieorres = '1' then 'Y' WHEN iecat = 'INCL' AND ieorres = '0' then 'Y' END as ie_violation FROM df: No matching data found. Passing 'SELECT * , CASE WHEN iecat = 'EXCL' AND ieorres = '1' then 'Y' WHEN iecat = 'INCL' AND ieorres = '0' then 'Y' END as ie_violation FROM df' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 38626 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 38626x6 data.frame saved as `lData$ie_violation`.
#>
#> ── Workflow Step 2 of 2: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = ie_violation: Passing lData$ie_violation.
#> ℹ strQuery = SELECT * FROM df WHERE subjid IS NOT NULL AND ie_violation = 'Y': No matching data found. Passing 'SELECT * FROM df WHERE subjid IS NOT NULL AND ie_violation = 'Y'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 0 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 0x6 data.frame saved as `lData$Mapped_IE`.
#>
#> ── Returning results from final step: 0x6 data.frame`. ──
#>
#> ── Completed `Mapped_IE` Workflow ──────────────────────────────────────────────
#>
#> ── Initializing `Mapped_LB` Workflow ───────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_LB
#> → All specified columns in Raw_LB are in the expected format
#> → All 4 specified column(s) in the spec are present in the data: Raw_LB$subjid, Raw_LB$toxgrg_nsv, Raw_LB$lb_dt, Raw_LB$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_LB: No matching data found. Passing 'Mapped_LB' as a string.
#> ✔ rhs = Raw_LB: Passing lData$Raw_LB.
#>
#> ── Calling `=`
#>
#> ── 1457497x4 data.frame saved as `lData$Mapped_LB`.
#>
#> ── Returning results from final step: 1457497x4 data.frame`. ──
#>
#> ── Completed `Mapped_LB` Workflow ──────────────────────────────────────────────
#>
#> ── Initializing `Mapped_PD` Workflow ───────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_PD
#> → All specified columns in Raw_PD are in the expected format
#> → All 5 specified column(s) in the spec are present in the data: Raw_PD$subjid, Raw_PD$deemedimportant, Raw_PD$deviationdate, Raw_PD$companycategory, Raw_PD$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_PD: No matching data found. Passing 'Mapped_PD' as a string.
#> ✔ rhs = Raw_PD: Passing lData$Raw_PD.
#>
#> ── Calling `=`
#>
#> ── 5720x5 data.frame saved as `lData$Mapped_PD`.
#>
#> ── Returning results from final step: 5720x5 data.frame`. ──
#>
#> ── Completed `Mapped_PD` Workflow ──────────────────────────────────────────────
#>
#> ── Initializing `Mapped_Randomization` Workflow ────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_Randomization
#> → All specified columns in Raw_Randomization are in the expected format
#> → All 6 specified column(s) in the spec are present in the data: Raw_Randomization$studyid, Raw_Randomization$invid, Raw_Randomization$subjid, Raw_Randomization$rand_dt, Raw_Randomization$status, Raw_Randomization$country
#>
#> ── Workflow Step 1 of 1: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_Randomization: Passing lData$Raw_Randomization.
#> ℹ strQuery = SELECT  studyid, invid, subjid, rand_dt, status, country FROM df WHERE subjid IS NOT NULL AND (status != 'Screen Failed' OR status IS NULL): No matching data found. Passing 'SELECT  studyid, invid, subjid, rand_dt, status, country FROM df WHERE subjid IS NOT NULL AND (status != 'Screen Failed' OR status IS NULL)' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1661x6 data.frame saved as `lData$Mapped_Randomization`.
#>
#> ── Returning results from final step: 1661x6 data.frame`. ──
#>
#> ── Completed `Mapped_Randomization` Workflow ───────────────────────────────────
#>
#> ── Initializing `Mapped_SDRGCOMP` Workflow ─────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_SDRGCOMP
#> → All specified columns in Raw_SDRGCOMP are in the expected format
#> → All 5 specified column(s) in the spec are present in the data: Raw_SDRGCOMP$subjid, Raw_SDRGCOMP$sdrgyn, Raw_SDRGCOMP$phase, Raw_SDRGCOMP$mincreated_dts, Raw_SDRGCOMP$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_SDRGCOMP: No matching data found. Passing 'Mapped_SDRGCOMP' as a string.
#> ✔ rhs = Raw_SDRGCOMP: Passing lData$Raw_SDRGCOMP.
#>
#> ── Calling `=`
#>
#> ── 876x5 data.frame saved as `lData$Mapped_SDRGCOMP`.
#>
#> ── Returning results from final step: 876x5 data.frame`. ──
#>
#> ── Completed `Mapped_SDRGCOMP` Workflow ────────────────────────────────────────
#>
#> ── Initializing `Mapped_STUDCOMP` Workflow ─────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_STUDCOMP
#> → All specified columns in Raw_STUDCOMP are in the expected format
#> → All 5 specified column(s) in the spec are present in the data: Raw_STUDCOMP$subjid, Raw_STUDCOMP$compyn, Raw_STUDCOMP$compreas, Raw_STUDCOMP$mincreated_dts, Raw_STUDCOMP$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_STUDCOMP: No matching data found. Passing 'Mapped_STUDCOMP' as a string.
#> ✔ rhs = Raw_STUDCOMP: Passing lData$Raw_STUDCOMP.
#>
#> ── Calling `=`
#>
#> ── 154x5 data.frame saved as `lData$Mapped_STUDCOMP`.
#>
#> ── Returning results from final step: 154x5 data.frame`. ──
#>
#> ── Completed `Mapped_STUDCOMP` Workflow ────────────────────────────────────────
#>
#> ── Initializing `Mapped_StudyRef` Workflow ─────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_StudyRef
#> → All specified columns in Raw_StudyRef are in the expected format
#> → All 2 specified column(s) in the spec are present in the data: Raw_StudyRef$studyid, Raw_StudyRef$studyrefid
#>
#> ── Workflow Step 1 of 1: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_StudyRef: Passing lData$Raw_StudyRef.
#> ℹ strQuery = SELECT studyid AS study, studyrefid AS studyref FROM df: No matching data found. Passing 'SELECT studyid AS study, studyrefid AS studyref FROM df' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 7 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 7x2 data.frame saved as `lData$Mapped_StudyRef`.
#>
#> ── Returning results from final step: 7x2 data.frame`. ──
#>
#> ── Completed `Mapped_StudyRef` Workflow ────────────────────────────────────────
#>
#> ── Initializing `Mapped_SUBJ` Workflow ─────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_SUBJ
#> → All specified columns in Raw_SUBJ are in the expected format
#> → All 14 specified column(s) in the spec are present in the data: Raw_SUBJ$studyid, Raw_SUBJ$invid, Raw_SUBJ$country, Raw_SUBJ$subjid, Raw_SUBJ$subject_nsv, Raw_SUBJ$enrollyn, Raw_SUBJ$timeonstudy, Raw_SUBJ$firstparticipantdate, Raw_SUBJ$lastparticipantdate, Raw_SUBJ$firstdosedate, Raw_SUBJ$timeontreatment, Raw_SUBJ$agerep, Raw_SUBJ$sex, Raw_SUBJ$race
#>
#> ── Workflow Step 1 of 1: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_SUBJ: Passing lData$Raw_SUBJ.
#> ℹ strQuery = SELECT * FROM df WHERE enrollyn == 'Y': No matching data found. Passing 'SELECT * FROM df WHERE enrollyn == 'Y'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1661x14 data.frame saved as `lData$Mapped_SUBJ`.
#>
#> ── Returning results from final step: 1661x14 data.frame`. ──
#>
#> ── Completed `Mapped_SUBJ` Workflow ────────────────────────────────────────────
#>
#> ── Initializing `Mapped_Visit` Workflow ────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Raw_VISIT
#> → All specified columns in Raw_VISIT are in the expected format
#> → All 6 specified column(s) in the spec are present in the data: Raw_VISIT$subjid, Raw_VISIT$visit_dt, Raw_VISIT$visit_folder, Raw_VISIT$invid, Raw_VISIT$peperf, Raw_VISIT$studyid
#>
#> ── Workflow Step 1 of 1: `=` ──
#>
#> ── Evaluating 2 parameter(s) for `=`
#> ℹ lhs = Mapped_VISIT: No matching data found. Passing 'Mapped_VISIT' as a string.
#> ✔ rhs = Raw_VISIT: Passing lData$Raw_VISIT.
#>
#> ── Calling `=`
#>
#> ── 36113x6 data.frame saved as `lData$Mapped_VISIT`.
#>
#> ── Returning results from final step: 36113x6 data.frame`. ──
#>
#> ── Completed `Mapped_Visit` Workflow ───────────────────────────────────────────
#>
#> ── Initializing `Mapped_DATACHG` Workflow ──────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 3 data.frame(s) in the spec are present in the data: Raw_DATACHG, Raw_DATAENT, Mapped_SUBJ
#> → All specified columns in Raw_DATACHG are in the expected format
#> → All specified columns in Raw_DATAENT are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 14 specified column(s) in the spec are present in the data: Raw_DATACHG$studyid, Raw_DATACHG$subject_nsv, Raw_DATACHG$n_changes, Raw_DATACHG$visit_date, Raw_DATACHG$visit, Raw_DATACHG$formoid, Raw_DATAENT$studyid, Raw_DATAENT$subject_nsv, Raw_DATAENT$formoid, Raw_DATAENT$min_entereddate, Raw_DATAENT$visit, Mapped_SUBJ$studyid, Mapped_SUBJ$subjid, Mapped_SUBJ$subject_nsv
#>
#> ── Workflow Step 1 of 3: `dplyr::select` ──
#>
#> ── Evaluating 4 parameter(s) for `dplyr::select`
#> ✔ .data = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ subjid = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ subject_nsv = subject_nsv: No matching data found. Passing 'subject_nsv' as a string.
#> ℹ studyid = studyid: No matching data found. Passing 'studyid' as a string.
#>
#> ── Calling `dplyr::select`
#>
#> ── 1661x3 data.frame saved as `lData$Temp_SubjectLookup`.
#>
#> ── Workflow Step 2 of 3: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Raw_DATACHG: Passing lData$Raw_DATACHG.
#> ✔ y = Temp_SubjectLookup: Passing lData$Temp_SubjectLookup.
#> ℹ by is of length 2: Parameter is a vector. Passing as is.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 2719904x7 data.frame saved as `lData$Temp_DATACHG`.
#>
#> ── Workflow Step 3 of 3: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Temp_DATACHG: Passing lData$Temp_DATACHG.
#> ✔ y = Raw_DATAENT: Passing lData$Raw_DATAENT.
#> ℹ by is of length 4: Parameter is a vector. Passing as is.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 2719904x9 data.frame saved as `lData$Mapped_DATACHG`.
#>
#> ── Returning results from final step: 2719904x9 data.frame`. ──
#>
#> ── Completed `Mapped_DATACHG` Workflow ─────────────────────────────────────────
#>
#> ── Initializing `Mapped_DATAENT` Workflow ──────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Raw_DATAENT, Mapped_SUBJ
#> → All specified columns in Raw_DATAENT are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 6 specified column(s) in the spec are present in the data: Raw_DATAENT$subject_nsv, Raw_DATAENT$data_entry_lag, Raw_DATAENT$min_entereddate, Raw_DATAENT$studyid, Mapped_SUBJ$subjid, Mapped_SUBJ$subject_nsv
#>
#> ── Workflow Step 1 of 2: `dplyr::select` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::select`
#> ✔ .data = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ subjid = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ subject_nsv = subject_nsv: No matching data found. Passing 'subject_nsv' as a string.
#>
#> ── Calling `dplyr::select`
#>
#> ── 1661x2 data.frame saved as `lData$Temp_SubjectLookup`.
#>
#> ── Workflow Step 2 of 2: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Raw_DATAENT: Passing lData$Raw_DATAENT.
#> ✔ y = Temp_SubjectLookup: Passing lData$Temp_SubjectLookup.
#> ℹ by = subject_nsv: No matching data found. Passing 'subject_nsv' as a string.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 318256x7 data.frame saved as `lData$Mapped_DATAENT`.
#>
#> ── Returning results from final step: 318256x7 data.frame`. ──
#>
#> ── Completed `Mapped_DATAENT` Workflow ─────────────────────────────────────────
#>
#> ── Initializing `Mapped_EXCLUSION` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 3 data.frame(s) in the spec are present in the data: Mapped_IE, Mapped_ENROLL, Mapped_PD
#> → All specified columns in Mapped_IE are in the expected format
#> → All specified columns in Mapped_ENROLL are in the expected format
#> → All specified columns in Mapped_PD are in the expected format
#> → All 18 specified column(s) in the spec are present in the data: Mapped_IE$studyid, Mapped_IE$subjid, Mapped_IE$tiver, Mapped_IE$ieorres, Mapped_IE$iecat, Mapped_IE$ie_violation, Mapped_ENROLL$studyid, Mapped_ENROLL$subjectid, Mapped_ENROLL$subjid, Mapped_ENROLL$invid, Mapped_ENROLL$enrollyn, Mapped_ENROLL$country, Mapped_ENROLL$enroll_dt, Mapped_PD$studyid, Mapped_PD$subjid, Mapped_PD$companycategory, Mapped_PD$deemedimportant, Mapped_PD$deviationdate
#>
#> ── Workflow Step 1 of 5: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_IE: Passing lData$Mapped_IE.
#> ℹ strQuery = SELECT subjid, studyid, array_to_string(array_agg(iecat), ',') AS iecat_concat, ie_violation FROM df GROUP BY studyid, subjid, ie_violation: No matching data found. Passing 'SELECT subjid, studyid, array_to_string(array_agg(iecat), ',') AS iecat_concat, ie_violation FROM df GROUP BY studyid, subjid, ie_violation' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 0 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 0x4 data.frame saved as `lData$pivot_ie`.
#>
#> ── Workflow Step 2 of 5: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Mapped_ENROLL: Passing lData$Mapped_ENROLL.
#> ✔ y = pivot_ie: Passing lData$pivot_ie.
#> ℹ by is of length 2: Parameter is a vector. Passing as is.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 3641x9 data.frame saved as `lData$add_ie`.
#>
#> ── Workflow Step 3 of 5: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_PD: Passing lData$Mapped_PD.
#> ℹ strQuery = SELECT DISTINCT studyid, subjid, companycategory FROM df WHERE companycategory = 'ELIGIBILITY CRITERIA': No matching data found. Passing 'SELECT DISTINCT studyid, subjid, companycategory FROM df WHERE companycategory = 'ELIGIBILITY CRITERIA'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 69 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 69x3 data.frame saved as `lData$pivot_pd`.
#>
#> ── Workflow Step 4 of 5: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = add_ie: Passing lData$add_ie.
#> ✔ y = pivot_pd: Passing lData$pivot_pd.
#> ℹ by is of length 2: Parameter is a vector. Passing as is.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 3641x10 data.frame saved as `lData$premapped`.
#>
#> ── Workflow Step 5 of 5: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = premapped: Passing lData$premapped.
#> ℹ strQuery = SELECT *, CASE WHEN ie_violation = 'Y' AND companycategory IS NULL THEN 'EDC I/E' WHEN ie_violation IS NULL AND companycategory IS NOT NULL THEN 'Eligibility IPD' WHEN ie_violation = 'Y' AND companycategory IS NOT NULL THEN 'Ineligible, Both Criteria' ELSE 'Neither' END AS Source  FROM df WHERE enrollyn = 'Y': No matching data found. Passing 'SELECT *, CASE WHEN ie_violation = 'Y' AND companycategory IS NULL THEN 'EDC I/E' WHEN ie_violation IS NULL AND companycategory IS NOT NULL THEN 'Eligibility IPD' WHEN ie_violation = 'Y' AND companycategory IS NOT NULL THEN 'Ineligible, Both Criteria' ELSE 'Neither' END AS Source  FROM df WHERE enrollyn = 'Y'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1661 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1661x11 data.frame saved as `lData$Mapped_EXCLUSION`.
#>
#> ── Returning results from final step: 1661x11 data.frame`. ──
#>
#> ── Completed `Mapped_EXCLUSION` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Mapped_QUERY` Workflow ────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Raw_QUERY, Mapped_SUBJ
#> → All specified columns in Raw_QUERY are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Raw_QUERY$subject_nsv, Raw_QUERY$querystatus, Raw_QUERY$queryage, Raw_QUERY$created, Raw_QUERY$resolved, Raw_QUERY$studyid, Mapped_SUBJ$subjid, Mapped_SUBJ$subject_nsv
#>
#> ── Workflow Step 1 of 2: `dplyr::select` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::select`
#> ✔ .data = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ subjid = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ subject_nsv = subject_nsv: No matching data found. Passing 'subject_nsv' as a string.
#>
#> ── Calling `dplyr::select`
#>
#> ── 1661x2 data.frame saved as `lData$Temp_SubjectLookup`.
#>
#> ── Workflow Step 2 of 2: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Raw_QUERY: Passing lData$Raw_QUERY.
#> ✔ y = Temp_SubjectLookup: Passing lData$Temp_SubjectLookup.
#> ℹ by = subject_nsv: No matching data found. Passing 'subject_nsv' as a string.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 54606x7 data.frame saved as `lData$Mapped_QUERY`.
#>
#> ── Returning results from final step: 54606x7 data.frame`. ──
#>
#> ── Completed `Mapped_QUERY` Workflow ───────────────────────────────────────────
#>
#> ── Initializing `Mapped_COUNTRY` Workflow ──────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Mapped_SUBJ
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 3 specified column(s) in the spec are present in the data: Mapped_SUBJ$country, Mapped_SUBJ$invid, Mapped_SUBJ$subjid
#>
#> ── Workflow Step 1 of 2: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strQuery = SELECT country as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df GROUP BY country: No matching data found. Passing 'SELECT country as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df GROUP BY country' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 3 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 3x3 data.frame saved as `lData$Temp_CountryCountsWide`.
#>
#> ── Workflow Step 2 of 2: `gsm.mapping::MakeLongMeta` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.mapping::MakeLongMeta`
#> ✔ data = Temp_CountryCountsWide: Passing lData$Temp_CountryCountsWide.
#> ℹ strGroupLevel = Country: No matching data found. Passing 'Country' as a string.
#>
#> ── Calling `gsm.mapping::MakeLongMeta`
#>
#> ── 6x4 data.frame saved as `lData$Mapped_COUNTRY`.
#>
#> ── Returning results from final step: 6x4 data.frame`. ──
#>
#> ── Completed `Mapped_COUNTRY` Workflow ─────────────────────────────────────────
#>
#> ── Initializing `Mapped_SITE` Workflow ─────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Raw_SITE, Mapped_SUBJ
#> → All specified columns in Raw_SITE are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 11 specified column(s) in the spec are present in the data: Raw_SITE$studyid, Raw_SITE$invid, Raw_SITE$InvestigatorFirstName, Raw_SITE$InvestigatorLastName, Raw_SITE$site_status, Raw_SITE$City, Raw_SITE$State, Raw_SITE$Country, Mapped_SUBJ$studyid, Mapped_SUBJ$invid, Mapped_SUBJ$subjid
#>
#> ── Workflow Step 1 of 5: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_SITE: Passing lData$Raw_SITE.
#> ℹ strQuery = SELECT invid as GroupID, * FROM df: No matching data found. Passing 'SELECT invid as GroupID, * FROM df' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 632 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 632x9 data.frame saved as `lData$Temp_CTMSSiteWide`.
#>
#> ── Workflow Step 2 of 5: `gsm.mapping::MakeLongMeta` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.mapping::MakeLongMeta`
#> ✔ data = Temp_CTMSSiteWide: Passing lData$Temp_CTMSSiteWide.
#> ℹ strGroupLevel = Site: No matching data found. Passing 'Site' as a string.
#>
#> ── Calling `gsm.mapping::MakeLongMeta`
#>
#> ── 5056x4 data.frame saved as `lData$Temp_CTMSSite`.
#>
#> ── Workflow Step 3 of 5: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strQuery = SELECT invid as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df GROUP BY invid: No matching data found. Passing 'SELECT invid as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df GROUP BY invid' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 591 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 591x3 data.frame saved as `lData$Temp_SiteCountsWide`.
#>
#> ── Workflow Step 4 of 5: `gsm.mapping::MakeLongMeta` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.mapping::MakeLongMeta`
#> ✔ data = Temp_SiteCountsWide: Passing lData$Temp_SiteCountsWide.
#> ℹ strGroupLevel = Site: No matching data found. Passing 'Site' as a string.
#>
#> ── Calling `gsm.mapping::MakeLongMeta`
#>
#> ── 1182x4 data.frame saved as `lData$Temp_SiteCounts`.
#>
#> ── Workflow Step 5 of 5: `dplyr::bind_rows` ──
#>
#> ── Evaluating 2 parameter(s) for `dplyr::bind_rows`
#> ✔ Temp_CTMSSite = Temp_CTMSSite: Passing lData$Temp_CTMSSite.
#> ✔ Temp_SiteCounts = Temp_SiteCounts: Passing lData$Temp_SiteCounts.
#>
#> ── Calling `dplyr::bind_rows`
#>
#> ── 6238x4 data.frame saved as `lData$Mapped_SITE`.
#>
#> ── Returning results from final step: 6238x4 data.frame`. ──
#>
#> ── Completed `Mapped_SITE` Workflow ────────────────────────────────────────────
#>
#> ── Initializing `Mapped_STUDY` Workflow ────────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Raw_STUDY, Raw_SUBJ
#> → All specified columns in Raw_STUDY are in the expected format
#> → All specified columns in Raw_SUBJ are in the expected format
#> → All 18 specified column(s) in the spec are present in the data: Raw_STUDY$studyid, Raw_STUDY$nickname, Raw_STUDY$protocol_title, Raw_STUDY$status, Raw_STUDY$num_plan_site, Raw_STUDY$num_plan_subj, Raw_STUDY$act_fpfv, Raw_STUDY$est_fpfv, Raw_STUDY$est_lplv, Raw_STUDY$est_lpfv, Raw_STUDY$therapeutic_area, Raw_STUDY$protocol_indication, Raw_STUDY$phase, Raw_STUDY$product, Raw_SUBJ$studyid, Raw_SUBJ$invid, Raw_SUBJ$subjid, Raw_SUBJ$enrollyn
#>
#> ── Workflow Step 1 of 9: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_STUDY: Passing lData$Raw_STUDY.
#> ℹ strQuery = SELECT studyid as GroupID, * FROM df: No matching data found. Passing 'SELECT studyid as GroupID, * FROM df' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 6 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 6x15 data.frame saved as `lData$Temp_CTMSStudyWide`.
#>
#> ── Workflow Step 2 of 9: `gsm.mapping::MakeLongMeta` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.mapping::MakeLongMeta`
#> ✔ data = Temp_CTMSStudyWide: Passing lData$Temp_CTMSStudyWide.
#> ℹ strGroupLevel = Study: No matching data found. Passing 'Study' as a string.
#>
#> ── Calling `gsm.mapping::MakeLongMeta`
#>
#> ── 84x4 data.frame saved as `lData$Temp_CTMSStudy`.
#>
#> ── Workflow Step 3 of 9: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_STUDY: Passing lData$Raw_STUDY.
#> ℹ strQuery = SELECT studyid as GroupID, num_plan_site as SiteTarget, num_plan_subj as ParticipantTarget FROM df: No matching data found. Passing 'SELECT studyid as GroupID, num_plan_site as SiteTarget, num_plan_subj as ParticipantTarget FROM df' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 6 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 6x3 data.frame saved as `lData$Temp_CTMSplanned`.
#>
#> ── Workflow Step 4 of 9: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Raw_SUBJ: Passing lData$Raw_SUBJ.
#> ℹ strQuery = SELECT studyid as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df WHERE enrollyn == 'Y' GROUP BY studyid: No matching data found. Passing 'SELECT studyid as GroupID, COUNT(DISTINCT subjid) as ParticipantCount, COUNT(DISTINCT invid) as SiteCount FROM df WHERE enrollyn == 'Y' GROUP BY studyid' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 6 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 6x3 data.frame saved as `lData$Temp_StudyCountsWide`.
#>
#> ── Workflow Step 5 of 9: `dplyr::left_join` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::left_join`
#> ✔ x = Temp_CTMSplanned: Passing lData$Temp_CTMSplanned.
#> ✔ y = Temp_StudyCountsWide: Passing lData$Temp_StudyCountsWide.
#> ℹ by = GroupID: No matching data found. Passing 'GroupID' as a string.
#>
#> ── Calling `dplyr::left_join`
#>
#> ── 6x5 data.frame saved as `lData$Temp_CountTargetsWide`.
#>
#> ── Workflow Step 6 of 9: `gsm.mapping::CalculatePercentage` ──
#>
#> ── Evaluating 5 parameter(s) for `gsm.mapping::CalculatePercentage`
#> ✔ data = Temp_CountTargetsWide: Passing lData$Temp_CountTargetsWide.
#> ℹ strCurrentCol = SiteCount: No matching data found. Passing 'SiteCount' as a string.
#> ℹ strTargetCol = SiteTarget: No matching data found. Passing 'SiteTarget' as a string.
#> ℹ strPercVal = PercentSitesActivated: No matching data found. Passing 'PercentSitesActivated' as a string.
#> ℹ strPercStrVal = SiteActivation: No matching data found. Passing 'SiteActivation' as a string.
#>
#> ── Calling `gsm.mapping::CalculatePercentage`
#>
#> ── 6x7 data.frame saved as `lData$Temp_CountTargetsWide_addsite`.
#>
#> ── Workflow Step 7 of 9: `gsm.mapping::CalculatePercentage` ──
#>
#> ── Evaluating 5 parameter(s) for `gsm.mapping::CalculatePercentage`
#> ✔ data = Temp_CountTargetsWide_addsite: Passing lData$Temp_CountTargetsWide_addsite.
#> ℹ strCurrentCol = ParticipantCount: No matching data found. Passing 'ParticipantCount' as a string.
#> ℹ strTargetCol = ParticipantTarget: No matching data found. Passing 'ParticipantTarget' as a string.
#> ℹ strPercVal = PercentParticipantsEnrolled: No matching data found. Passing 'PercentParticipantsEnrolled' as a string.
#> ℹ strPercStrVal = ParticipantEnrollment: No matching data found. Passing 'ParticipantEnrollment' as a string.
#>
#> ── Calling `gsm.mapping::CalculatePercentage`
#>
#> ── 6x9 data.frame saved as `lData$Temp_CountTargetsWide_addsitepts`.
#>
#> ── Workflow Step 8 of 9: `gsm.mapping::MakeLongMeta` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.mapping::MakeLongMeta`
#> ✔ data = Temp_CountTargetsWide_addsitepts: Passing lData$Temp_CountTargetsWide_addsitepts.
#> ℹ strGroupLevel = Study: No matching data found. Passing 'Study' as a string.
#>
#> ── Calling `gsm.mapping::MakeLongMeta`
#>
#> ── 48x4 data.frame saved as `lData$Temp_CountTargetsPercs`.
#>
#> ── Workflow Step 9 of 9: `dplyr::bind_rows` ──
#>
#> ── Evaluating 2 parameter(s) for `dplyr::bind_rows`
#> ✔ Temp_CTMSStudy = Temp_CTMSStudy: Passing lData$Temp_CTMSStudy.
#> ✔ Temp_CountTargetsPercs = Temp_CountTargetsPercs: Passing lData$Temp_CountTargetsPercs.
#>
#> ── Calling `dplyr::bind_rows`
#>
#> ── 132x4 data.frame saved as `lData$Mapped_STUDY`.
#>
#> ── Returning results from final step: 132x4 data.frame`. ──
#>
#> ── Completed `Mapped_STUDY` Workflow ───────────────────────────────────────────


# Run KRI workflow
metrics_wf <- gsm.core::MakeWorkflowList(
  strNames = NULL,
  strPath = system.file("workflow/2_metrics", package = "gsm.studykri"),
  strPackage = NULL
)

# Combine lMapped with metrics workflows for comprehensive result
lAnalyzed <- gsm.core::RunWorkflows(lWorkflows = metrics_wf, lData = lMapped)
#>
#> ── Running 14 Workflows ────────────────────────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0001` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_AE, Mapped_SUBJ
#> → All specified columns in Mapped_AE are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 7 specified column(s) in the spec are present in the data: Mapped_AE$subjid, Mapped_AE$aest_dt, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 3: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 12 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Mapped_AE: Passing lData$Mapped_AE.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = aest_dt: No matching data found. Passing 'aest_dt' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ℹ strDenominatorEndDateCol = lastparticipantdate: No matching data found. Passing 'lastparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 32420x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 2 of 3: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1121x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 3 of 3: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0001` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0002` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_AE, Mapped_SUBJ
#> → All specified columns in Mapped_AE are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_AE$subjid, Mapped_AE$aest_dt, Mapped_AE$aeser, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_AE: Passing lData$Mapped_AE.
#> ℹ strQuery = SELECT *
#> FROM df
#> WHERE aeser = 'Y'
#> : No matching data found. Passing 'SELECT *
#> FROM df
#> WHERE aeser = 'Y'
#> ' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 171 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 171x8 data.frame saved as `lData$Mapped_SAE`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 12 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Mapped_SAE: Passing lData$Mapped_SAE.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = aest_dt: No matching data found. Passing 'aest_dt' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ℹ strDenominatorEndDateCol = lastparticipantdate: No matching data found. Passing 'lastparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 32420x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1121x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0002` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0003` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_PD, Mapped_SUBJ
#> → All specified columns in Mapped_PD are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_PD$subjid, Mapped_PD$deemedimportant, Mapped_PD$deviationdate, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_PD: Passing lData$Mapped_PD.
#> ℹ strQuery = SELECT * FROM df WHERE deemedimportant = 'No': No matching data found. Passing 'SELECT * FROM df WHERE deemedimportant = 'No'' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 5141 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 5141x5 data.frame saved as `lData$Temp_NONIMPORTANT`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 12 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_NONIMPORTANT: Passing lData$Temp_NONIMPORTANT.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = deviationdate: No matching data found. Passing 'deviationdate' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ℹ strDenominatorEndDateCol = lastparticipantdate: No matching data found. Passing 'lastparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 32572x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1121x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0003` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0004` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_PD, Mapped_SUBJ
#> → All specified columns in Mapped_PD are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_PD$subjid, Mapped_PD$deemedimportant, Mapped_PD$deviationdate, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_PD: Passing lData$Mapped_PD.
#> ℹ strQuery = SELECT * FROM df WHERE deemedimportant = 'Yes': No matching data found. Passing 'SELECT * FROM df WHERE deemedimportant = 'Yes'' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 579 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 579x5 data.frame saved as `lData$Temp_IMPORTANT`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 12 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_IMPORTANT: Passing lData$Temp_IMPORTANT.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = deviationdate: No matching data found. Passing 'deviationdate' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ℹ strDenominatorEndDateCol = lastparticipantdate: No matching data found. Passing 'lastparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 32433x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1121x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0004` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0005` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_SUBJ, Mapped_LB
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All specified columns in Mapped_LB are in the expected format
#> → All 5 specified column(s) in the spec are present in the data: Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_LB$subjid, Mapped_LB$toxgrg_nsv, Mapped_LB$lb_dt
#>
#> ── Workflow Step 1 of 5: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_LB: Passing lData$Mapped_LB.
#> ℹ strQuery = SELECT * FROM df WHERE toxgrg_nsv IN ('3', '4'): No matching data found. Passing 'SELECT * FROM df WHERE toxgrg_nsv IN ('3', '4')' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1861 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1861x4 data.frame saved as `lData$Temp_ABNORMAL`.
#>
#> ── Workflow Step 2 of 5: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_LB: Passing lData$Mapped_LB.
#> ℹ strQuery = SELECT * FROM df WHERE toxgrg_nsv IN ('0', '1', '2', '3', '4'): No matching data found. Passing 'SELECT * FROM df WHERE toxgrg_nsv IN ('0', '1', '2', '3', '4')' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 735123 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 735123x4 data.frame saved as `lData$Temp_LB`.
#>
#> ── Workflow Step 3 of 5: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_ABNORMAL: Passing lData$Temp_ABNORMAL.
#> ✔ dfDenominator = Temp_LB: Passing lData$Temp_LB.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = lb_dt: No matching data found. Passing 'lb_dt' as a string.
#> ℹ strDenominatorDateCol = lb_dt: No matching data found. Passing 'lb_dt' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 25894x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 4 of 5: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1132x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 5 of 5: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0005` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0006` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_STUDCOMP, Mapped_SUBJ
#> → All specified columns in Mapped_STUDCOMP are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_STUDCOMP$subjid, Mapped_STUDCOMP$compyn, Mapped_STUDCOMP$mincreated_dts, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_STUDCOMP: Passing lData$Mapped_STUDCOMP.
#> ℹ strQuery = SELECT * FROM df WHERE compyn = 'N': No matching data found. Passing 'SELECT * FROM df WHERE compyn = 'N'' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 137 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 137x5 data.frame saved as `lData$Temp_DROPOUT`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_DROPOUT: Passing lData$Temp_DROPOUT.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = mincreated_dts: No matching data found. Passing 'mincreated_dts' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 1758x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1017x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0006` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0007` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_SDRGCOMP, Mapped_SUBJ
#> → All specified columns in Mapped_SDRGCOMP are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 9 specified column(s) in the spec are present in the data: Mapped_SDRGCOMP$subjid, Mapped_SDRGCOMP$sdrgyn, Mapped_SDRGCOMP$phase, Mapped_SDRGCOMP$mincreated_dts, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_SDRGCOMP: Passing lData$Mapped_SDRGCOMP.
#> ℹ strQuery = SELECT * FROM df WHERE sdrgyn = 'N': No matching data found. Passing 'SELECT * FROM df WHERE sdrgyn = 'N'' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 153 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 153x5 data.frame saved as `lData$Temp_DISCONTINUED`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_DISCONTINUED: Passing lData$Temp_DISCONTINUED.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = mincreated_dts: No matching data found. Passing 'mincreated_dts' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 1774x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1036x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0007` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0008` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 3 data.frame(s) in the spec are present in the data: Mapped_QUERY, Mapped_DATACHG, Mapped_SUBJ
#> → All specified columns in Mapped_QUERY are in the expected format
#> → All specified columns in Mapped_DATACHG are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 10 specified column(s) in the spec are present in the data: Mapped_QUERY$subjid, Mapped_QUERY$querystatus, Mapped_QUERY$created, Mapped_DATACHG$subjid, Mapped_DATACHG$min_entereddate, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_QUERY: Passing lData$Mapped_QUERY.
#> ℹ strQuery = SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed'): No matching data found. Passing 'SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed')' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 54606 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 54606x7 data.frame saved as `lData$Temp_QUERY`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_QUERY: Passing lData$Temp_QUERY.
#> ✔ dfDenominator = Mapped_DATACHG: Passing lData$Mapped_DATACHG.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = created: No matching data found. Passing 'created' as a string.
#> ℹ strDenominatorDateCol = min_entereddate: No matching data found. Passing 'min_entereddate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 30075x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1125x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0008` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0009` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_QUERY, Mapped_SUBJ
#> → All specified columns in Mapped_QUERY are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 9 specified column(s) in the spec are present in the data: Mapped_QUERY$subjid, Mapped_QUERY$querystatus, Mapped_QUERY$created, Mapped_QUERY$queryage, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 5: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_QUERY: Passing lData$Mapped_QUERY.
#> ℹ strQuery = SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed') AND queryage > 30: No matching data found. Passing 'SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed') AND queryage > 30' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1074 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1074x7 data.frame saved as `lData$Temp_OLDQUERY`.
#>
#> ── Workflow Step 2 of 5: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_QUERY: Passing lData$Mapped_QUERY.
#> ℹ strQuery = SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed'): No matching data found. Passing 'SELECT * FROM df WHERE querystatus IN ('Open','Answered','Closed')' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 54606 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 54606x7 data.frame saved as `lData$Temp_QUERY`.
#>
#> ── Workflow Step 3 of 5: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_OLDQUERY: Passing lData$Temp_OLDQUERY.
#> ✔ dfDenominator = Temp_QUERY: Passing lData$Temp_QUERY.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = created: No matching data found. Passing 'created' as a string.
#> ℹ strDenominatorDateCol = created: No matching data found. Passing 'created' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 21615x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 4 of 5: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1085x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 5 of 5: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0009` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0010` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_DATAENT, Mapped_SUBJ
#> → All specified columns in Mapped_DATAENT are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_DATAENT$subjid, Mapped_DATAENT$data_entry_lag, Mapped_DATAENT$min_entereddate, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_DATAENT: Passing lData$Mapped_DATAENT.
#> ℹ strQuery = SELECT * FROM df WHERE data_entry_lag > 10: No matching data found. Passing 'SELECT * FROM df WHERE data_entry_lag > 10' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 13398 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 13398x7 data.frame saved as `lData$Temp_LAG`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_LAG: Passing lData$Temp_LAG.
#> ✔ dfDenominator = Mapped_DATAENT: Passing lData$Mapped_DATAENT.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = min_entereddate: No matching data found. Passing 'min_entereddate' as a string.
#> ℹ strDenominatorDateCol = min_entereddate: No matching data found. Passing 'min_entereddate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 28273x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1119x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0010` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0011` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_DATACHG, Mapped_SUBJ
#> → All specified columns in Mapped_DATACHG are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_DATACHG$subjid, Mapped_DATACHG$min_entereddate, Mapped_DATACHG$n_changes, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_DATACHG: Passing lData$Mapped_DATACHG.
#> ℹ strQuery = SELECT * FROM df WHERE n_changes > 0: No matching data found. Passing 'SELECT * FROM df WHERE n_changes > 0' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 706869 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 706869x9 data.frame saved as `lData$Temp_CHANGED`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = Temp_CHANGED: Passing lData$Temp_CHANGED.
#> ✔ dfDenominator = Mapped_DATACHG: Passing lData$Mapped_DATACHG.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = min_entereddate: No matching data found. Passing 'min_entereddate' as a string.
#> ℹ strDenominatorDateCol = min_entereddate: No matching data found. Passing 'min_entereddate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 28301x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1125x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0011` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0012` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 1 data.frame(s) in the spec are present in the data: Mapped_ENROLL
#> → All specified columns in Mapped_ENROLL are in the expected format
#> → All 4 specified column(s) in the spec are present in the data: Mapped_ENROLL$subjectid, Mapped_ENROLL$invid, Mapped_ENROLL$enrollyn, Mapped_ENROLL$enroll_dt
#>
#> ── Workflow Step 1 of 4: `RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `RunQuery`
#> ✔ df = Mapped_ENROLL: Passing lData$Mapped_ENROLL.
#> ℹ strQuery = SELECT * FROM df WHERE enrollyn = 'N': No matching data found. Passing 'SELECT * FROM df WHERE enrollyn = 'N'' as a string.
#>
#> ── Calling `RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 1980 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 1980x7 data.frame saved as `lData$Temp_SCREENED`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_ENROLL: Passing lData$Mapped_ENROLL.
#> ✔ dfNumerator = Temp_SCREENED: Passing lData$Temp_SCREENED.
#> ✔ dfDenominator = Mapped_ENROLL: Passing lData$Mapped_ENROLL.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjectid: No matching data found. Passing 'subjectid' as a string.
#> ℹ strNumeratorDateCol = enroll_dt: No matching data found. Passing 'enroll_dt' as a string.
#> ℹ strDenominatorDateCol = enroll_dt: No matching data found. Passing 'enroll_dt' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 3261x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 997x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0012` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0013` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_Visit, Mapped_SUBJ
#> → All specified columns in Mapped_Visit are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 8 specified column(s) in the spec are present in the data: Mapped_Visit$subjid, Mapped_Visit$peperf, Mapped_Visit$visit_dt, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_Visit: Passing lData$Mapped_Visit.
#> ℹ strQuery = SELECT * FROM df WHERE peperf = 'Y': No matching data found. Passing 'SELECT * FROM df WHERE peperf = 'Y'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 10512 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 10512x6 data.frame saved as `lData$PK_Collected`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = PK_Collected: Passing lData$PK_Collected.
#> ✔ dfDenominator = Mapped_Visit: Passing lData$Mapped_Visit.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = visit_dt: No matching data found. Passing 'visit_dt' as a string.
#> ℹ strDenominatorDateCol = visit_dt: No matching data found. Passing 'visit_dt' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 25308x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 1076x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0013` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Analysis_kri0014` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Mapped_EXCLUSION, Mapped_SUBJ
#> → All specified columns in Mapped_EXCLUSION are in the expected format
#> → All specified columns in Mapped_SUBJ are in the expected format
#> → All 14 specified column(s) in the spec are present in the data: Mapped_EXCLUSION$subjid, Mapped_EXCLUSION$subjectid, Mapped_EXCLUSION$Source, Mapped_EXCLUSION$studyid, Mapped_EXCLUSION$invid, Mapped_EXCLUSION$country, Mapped_EXCLUSION$companycategory, Mapped_EXCLUSION$ie_violation, Mapped_EXCLUSION$enroll_dt, Mapped_SUBJ$subjid, Mapped_SUBJ$invid, Mapped_SUBJ$studyid, Mapped_SUBJ$firstparticipantdate, Mapped_SUBJ$lastparticipantdate
#>
#> ── Workflow Step 1 of 4: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Mapped_EXCLUSION: Passing lData$Mapped_EXCLUSION.
#> ℹ strQuery = SELECT * FROM df WHERE Source != 'Neither': No matching data found. Passing 'SELECT * FROM df WHERE Source != 'Neither'' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 18 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 18x11 data.frame saved as `lData$TEMP_VIOLATIONS`.
#>
#> ── Workflow Step 2 of 4: `gsm.studykri::Input_CountSiteByMonth` ──
#>
#> ── Evaluating 11 parameter(s) for `gsm.studykri::Input_CountSiteByMonth`
#> ✔ dfSubjects = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ✔ dfNumerator = TEMP_VIOLATIONS: Passing lData$TEMP_VIOLATIONS.
#> ✔ dfDenominator = Mapped_SUBJ: Passing lData$Mapped_SUBJ.
#> ℹ strStudyCol = studyid: No matching data found. Passing 'studyid' as a string.
#> ℹ strGroupCol = invid: No matching data found. Passing 'invid' as a string.
#> ✔ strGroupLevel = GroupLevel: Passing lMeta$GroupLevel.
#> ℹ strSubjectCol = subjid: No matching data found. Passing 'subjid' as a string.
#> ℹ strNumeratorDateCol = enroll_dt: No matching data found. Passing 'enroll_dt' as a string.
#> ℹ strDenominatorDateCol = firstparticipantdate: No matching data found. Passing 'firstparticipantdate' as a string.
#> ✔ strDenominatorType = Denominator: Passing lMeta$Denominator.
#> ✔ nMinDenominator = AccrualThreshold: Passing lMeta$AccrualThreshold.
#>
#> ── Calling `gsm.studykri::Input_CountSiteByMonth`
#>
#> ── 1622x8 data.frame saved as `lData$Analysis_Input`.
#>
#> ── Workflow Step 3 of 4: `gsm.studykri::Transform_CumCount` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::Transform_CumCount`
#> ✔ dfInput = Analysis_Input: Passing lData$Analysis_Input.
#> ℹ vBy = StudyID: No matching data found. Passing 'StudyID' as a string.
#>
#> ── Calling `gsm.studykri::Transform_CumCount`
#>
#> ── 982x7 data.frame saved as `lData$Analysis_Transformed`.
#>
#> ── Workflow Step 4 of 4: `list` ──
#>
#> ── Evaluating 3 parameter(s) for `list`
#> ✔ ID = ID: Passing lMeta$ID.
#> ✔ Analysis_Input = Analysis_Input: Passing lData$Analysis_Input.
#> ✔ Analysis_Transformed = Analysis_Transformed: Passing lData$Analysis_Transformed.
#>
#> ── Calling `list`
#>
#> ── list of length 3 saved as `lData$lAnalysis`.
#>
#> ── Returning results from final step: list of length 3`. ──
#>
#> ── Completed `Analysis_kri0014` Workflow ───────────────────────────────────────
Generate KRI report using scripts
and subsequently generate a KRI report using {gsm.reporting}.
We assemble some data needed for reporting.
dfInput <- gsm.studykri::BindResults(lAnalyzed, "Analysis_Input")

dfTransformed <- gsm.studykri::BindResults(lAnalyzed, "Analysis_Transformed")

dfMetrics <- gsm.reporting::MakeMetric(metrics_wf)

dfGroups <- dplyr::bind_rows(
  lMapped$Mapped_STUDY,
  lMapped$Mapped_SITE,
  lMapped$Country
)

dfStudyRef <- lMapped$Mapped_StudyRef

dfStudyRef
#>   study studyref
#> 1  AA-1     AA-3
#> 2  AA-1     AA-4
#> 3  AA-1     AA-5
#> 4  AA-2     AA-3
#> 5  AA-2     AA-4
#> 6  AA-2     AA-5
#> 7  AA-2     AA-6
In order to make the bootstrapping more efficient we can combine all KRI that use the same denominator.
lJoined <- gsm.studykri::JoinKRIByDenominator(dfInput, dfMetrics)

str(lJoined)
#> List of 8
#>  $ Days on Study      : tibble [32,584 × 9] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:32584] "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" ...
#>   ..$ GroupLevel                : chr [1:32584] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:32584] 31 30 29 30 30 31 30 28 31 30 ...
#>   ..$ StudyID                   : chr [1:32584] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:32584] 200705 200709 200802 200804 200809 ...
#>   ..$ Numerator_Analysis_kri0001: int [1:32584] 1 1 1 1 1 1 1 1 1 2 ...
#>   ..$ Numerator_Analysis_kri0002: int [1:32584] 0 0 0 0 0 0 0 0 0 0 ...
#>   ..$ Numerator_Analysis_kri0003: int [1:32584] 0 0 0 0 0 0 0 0 0 0 ...
#>   ..$ Numerator_Analysis_kri0004: int [1:32584] 0 0 0 0 0 0 0 0 0 0 ...
#>  $ Total Lab Samples  : tibble [25,894 × 6] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:25894] "AA-1_0X001" "AA-1_0X001" "AA-1_0X003" "AA-1_0X005" ...
#>   ..$ GroupLevel                : chr [1:25894] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:25894] 21 37 41 21 21 37 21 21 21 21 ...
#>   ..$ StudyID                   : chr [1:25894] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:25894] 200705 200706 200707 200505 201401 ...
#>   ..$ Numerator_Analysis_kri0005: int [1:25894] 2 3 1 1 1 1 1 1 1 1 ...
#>  $ Enrolled Subjects  : tibble [1,804 × 8] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:1804] "AA-1_0X003" "AA-1_0X013" "AA-1_0X023" "AA-1_0X029" ...
#>   ..$ GroupLevel                : chr [1:1804] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:1804] 0 0 0 0 0 0 0 0 0 0 ...
#>   ..$ StudyID                   : chr [1:1804] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:1804] 200506 200803 201706 201207 201010 ...
#>   ..$ Numerator_Analysis_kri0006: int [1:1804] 1 1 1 1 1 1 1 1 1 1 ...
#>   ..$ Numerator_Analysis_kri0007: int [1:1804] NA 1 1 1 1 1 NA NA 1 1 ...
#>   ..$ Numerator_Analysis_kri0014: int [1:1804] NA NA NA NA NA NA NA NA NA NA ...
#>  $ Total Data Points  : tibble [30,075 × 7] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:30075] "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" ...
#>   ..$ GroupLevel                : chr [1:30075] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:30075] 35 83 148 83 77 77 103 78 84 8 ...
#>   ..$ StudyID                   : chr [1:30075] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:30075] 200704 200705 200706 200707 200708 ...
#>   ..$ Numerator_Analysis_kri0008: int [1:30075] 3 3 3 2 3 1 2 1 2 1 ...
#>   ..$ Numerator_Analysis_kri0011: int [1:30075] 8 18 42 18 19 21 26 22 15 1 ...
#>  $ Total Queries      : tibble [21,615 × 6] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:21615] "AA-1_0X006" "AA-1_0X006" "AA-1_0X006" "AA-1_0X007" ...
#>   ..$ GroupLevel                : chr [1:21615] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:21615] 4 3 1 2 1 2 1 4 8 2 ...
#>   ..$ StudyID                   : chr [1:21615] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:21615] 201604 201706 201801 200705 201812 ...
#>   ..$ Numerator_Analysis_kri0009: int [1:21615] 1 1 1 1 1 1 1 1 1 1 ...
#>  $ Total Data Pages   : tibble [28,273 × 6] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:28273] "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" ...
#>   ..$ GroupLevel                : chr [1:28273] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:28273] 10 9 10 9 1 4 1 16 10 9 ...
#>   ..$ StudyID                   : chr [1:28273] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:28273] 200707 200709 200803 200804 200807 ...
#>   ..$ Numerator_Analysis_kri0010: int [1:28273] 2 2 1 1 1 3 1 1 2 1 ...
#>  $ Screened Subjects  : tibble [3,261 × 6] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:3261] "0X001" "0X001" "0X003" "0X004" ...
#>   ..$ GroupLevel                : chr [1:3261] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:3261] 1 1 1 1 1 1 1 1 1 1 ...
#>   ..$ StudyID                   : chr [1:3261] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:3261] 201008 201706 201705 200502 200607 ...
#>   ..$ Numerator_Analysis_kri0012: int [1:3261] 1 1 1 1 1 1 1 1 1 1 ...
#>  $ PK Samples Expected: tibble [25,308 × 6] (S3: tbl_df/tbl/data.frame)
#>   ..$ GroupID                   : chr [1:25308] "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" "AA-1_0X001" ...
#>   ..$ GroupLevel                : chr [1:25308] "Site" "Site" "Site" "Site" ...
#>   ..$ Denominator               : int [1:25308] 1 1 2 1 1 1 1 2 1 2 ...
#>   ..$ StudyID                   : chr [1:25308] "AA-1" "AA-1" "AA-1" "AA-1" ...
#>   ..$ MonthYYYYMM               : num [1:25308] 200704 200705 200710 200804 200810 ...
#>   ..$ Numerator_Analysis_kri0013: int [1:25308] 1 1 1 1 1 1 1 1 1 1 ...
Using the study references we can calculate the bootstrapped confidence intervals for all KRI at once.
Bounds_Wide <- purrr::map(lJoined, ~ Analyze_StudyKRI_PredictBounds(., dfStudyRef))
BoundsRef_Wide <- purrr::map(lJoined, ~ Analyze_StudyKRI_PredictBoundsRef(., dfStudyRef))
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 146
#> Calculated minimum group count: 146
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69

dfBounds <- Transform_Long(Bounds_Wide)
dfBoundsRef <- Transform_Long(BoundsRef_Wide)
lCharts <- gsm.studykri::MakeCharts_StudyKRI(
  dfResults = dfTransformed,
  dfBounds = dfBounds,
  dfBoundsRef = dfBoundsRef,
  dfMetrics = dfMetrics
)

gsm.studykri::Report_StudyKRI(
  lCharts = lCharts,
  dfResults = dfTransformed,
  dfGroups = dfGroups,
  dfMetrics = dfMetrics,
  strOutputFile = "report_studykri.html",
  strInputPath = system.file("report", "Report_KRI.Rmd", package = "gsm.studykri")
)
#> processing file: Report_KRI.Rmd
#> output file: /tmp/RtmpUPTPVK/Report_KRI.knit.md
#> /opt/hostedtoolcache/pandoc/3.1.11/x64/pandoc +RTS -K512m -RTS /tmp/RtmpUPTPVK/Report_KRI.knit.md --to html4 --from markdown+autolink_bare_uris+tex_math_single_backslash --output /home/runner/work/gsm.studykri/gsm.studykri/vignettes/report_studykri_AA-1.html --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/pagebreak.lua --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/latex-div.lua --embed-resources --standalone --variable bs3=TRUE --section-divs --table-of-contents --toc-depth 3 --variable toc_float=1 --variable toc_selectors=h1,h2,h3 --variable toc_collapsed=1 --variable toc_smooth_scroll=1 --variable toc_print=1 --template /home/runner/work/_temp/Library/rmarkdown/rmd/h/default.html --no-highlight --variable highlightjs=1 --variable theme=flatly --mathjax --variable 'mathjax-url=https://mathjax.rstudio.com/latest/MathJax.js?config=TeX-AMS-MML_HTMLorMML' --include-in-header /tmp/RtmpUPTPVK/rmarkdown-str206739eac65f.html --variable code_folding=hide --variable code_menu=1
#>
#> Output created: report_studykri_AA-1.html
#> processing file: Report_KRI.Rmd
#> output file: /tmp/RtmpUPTPVK/Report_KRI.knit.md
#> /opt/hostedtoolcache/pandoc/3.1.11/x64/pandoc +RTS -K512m -RTS /tmp/RtmpUPTPVK/Report_KRI.knit.md --to html4 --from markdown+autolink_bare_uris+tex_math_single_backslash --output /home/runner/work/gsm.studykri/gsm.studykri/vignettes/report_studykri_AA-2.html --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/pagebreak.lua --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/latex-div.lua --embed-resources --standalone --variable bs3=TRUE --section-divs --table-of-contents --toc-depth 3 --variable toc_float=1 --variable toc_selectors=h1,h2,h3 --variable toc_collapsed=1 --variable toc_smooth_scroll=1 --variable toc_print=1 --template /home/runner/work/_temp/Library/rmarkdown/rmd/h/default.html --no-highlight --variable highlightjs=1 --variable theme=flatly --mathjax --variable 'mathjax-url=https://mathjax.rstudio.com/latest/MathJax.js?config=TeX-AMS-MML_HTMLorMML' --include-in-header /tmp/RtmpUPTPVK/rmarkdown-str20675b84d96b.html --variable code_folding=hide --variable code_menu=1
#>
#> Output created: report_studykri_AA-2.html
#>                        AA-1                        AA-2
#> "report_studykri_AA-1.html" "report_studykri_AA-2.html"
Generate KRI report using yaml workflows
reporting_wf <- gsm.core::MakeWorkflowList(
  strPath = system.file("workflow/3_reporting", package = "gsm.studykri")
)

# Pass both lMapped and lAnalyzed, plus workflows
lReporting <- gsm.core::RunWorkflows(
  lWorkflows = reporting_wf,
  lData = c(
    lMapped,
    list(
      lAnalyzed = lAnalyzed,
      lWorkflows = metrics_wf
    )
  )
)
#>
#> ── Running 7 Workflows ─────────────────────────────────────────────────────────
#>
#> ── Initializing `Reporting_Results` Workflow ───────────────────────────────────
#>
#> ── No spec found in workflow. Proceeding without checking data.
#>
#> ── Workflow Step 1 of 1: `gsm.studykri::BindResults` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::BindResults`
#> ✔ lAnalysis = lAnalyzed: Passing lData$lAnalyzed.
#> ℹ strName = Analysis_Transformed: No matching data found. Passing 'Analysis_Transformed' as a string.
#>
#> ── Calling `gsm.studykri::BindResults`
#>
#> ── 15178x9 data.frame saved as `lData$lResults`.
#>
#> ── Returning results from final step: 15178x9 data.frame`. ──
#>
#> ── Completed `Reporting_Results` Workflow ──────────────────────────────────────
#>
#> ── Initializing `Reporting_Groups` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 3 data.frame(s) in the spec are present in the data: Mapped_STUDY, Mapped_SITE, Mapped_COUNTRY
#> → No columns specified in the spec. All data.frames are pulling in all available columns.
#>
#> ── Workflow Step 1 of 1: `dplyr::bind_rows` ──
#>
#> ── Evaluating 3 parameter(s) for `dplyr::bind_rows`
#> ✔ Study = Mapped_STUDY: Passing lData$Mapped_STUDY.
#> ✔ Site = Mapped_SITE: Passing lData$Mapped_SITE.
#> ✔ Country = Mapped_COUNTRY: Passing lData$Mapped_COUNTRY.
#>
#> ── Calling `dplyr::bind_rows`
#>
#> ── 6376x4 data.frame saved as `lData$Reporting_Groups`.
#>
#> ── Returning results from final step: 6376x4 data.frame`. ──
#>
#> ── Completed `Reporting_Groups` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Reporting_Input` Workflow ─────────────────────────────────────
#>
#> ── No spec found in workflow. Proceeding without checking data.
#>
#> ── Workflow Step 1 of 1: `gsm.studykri::BindResults` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::BindResults`
#> ✔ lAnalysis = lAnalyzed: Passing lData$lAnalyzed.
#> ℹ strName = Analysis_Input: No matching data found. Passing 'Analysis_Input' as a string.
#>
#> ── Calling `gsm.studykri::BindResults`
#>
#> ── 297726x10 data.frame saved as `lData$Reporting_Input`.
#>
#> ── Returning results from final step: 297726x10 data.frame`. ──
#>
#> ── Completed `Reporting_Input` Workflow ────────────────────────────────────────
#>
#> ── Initializing `Reporting_Metrics` Workflow ───────────────────────────────────
#>
#> ── No spec found in workflow. Proceeding without checking data.
#>
#> ── Workflow Step 1 of 1: `gsm.reporting::MakeMetric` ──
#>
#> ── Evaluating 1 parameter(s) for `gsm.reporting::MakeMetric`
#> ✔ lWorkflows = lWorkflows: Passing lData$lWorkflows.
#>
#> ── Calling `gsm.reporting::MakeMetric`
#>
#> ── 14x16 data.frame saved as `lData$Reporting_Metrics`.
#>
#> ── Returning results from final step: 14x16 data.frame`. ──
#>
#> ── Completed `Reporting_Metrics` Workflow ──────────────────────────────────────
#>
#> ── Initializing `Reporting_Join` Workflow ──────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Reporting_Input, Reporting_Metrics
#> → All specified columns in Reporting_Input are in the expected format
#> → All 7 specified column(s) in the spec are present in the data: Reporting_Input$MetricID, Reporting_Input$GroupID, Reporting_Input$GroupLevel, Reporting_Input$Numerator, Reporting_Input$Denominator, Reporting_Input$StudyID, Reporting_Input$MonthYYYYMM
#>
#> ── Workflow Step 1 of 1: `gsm.studykri::JoinKRIByDenominator` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.studykri::JoinKRIByDenominator`
#> ✔ dfInput = Reporting_Input: Passing lData$Reporting_Input.
#> ✔ dfMetrics = Reporting_Metrics: Passing lData$Reporting_Metrics.
#>
#> ── Calling `gsm.studykri::JoinKRIByDenominator`
#>
#> ── list of length 8 saved as `lData$Joined_Analysis_Input`.
#>
#> ── Returning results from final step: list of length 8`. ──
#>
#> ── Completed `Reporting_Join` Workflow ─────────────────────────────────────────
#>
#> ── Initializing `Reporting_Bounds` Workflow ────────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Reporting_Join, Mapped_StudyRef
#> → All specified columns in Mapped_StudyRef are in the expected format
#> → All 2 specified column(s) in the spec are present in the data: Mapped_StudyRef$study, Mapped_StudyRef$studyref
#>
#> ── Workflow Step 1 of 3: `gsm.studykri::ParseFunction` ──
#>
#> ── Evaluating 1 parameter(s) for `gsm.studykri::ParseFunction`
#> ℹ strFunction = gsm.studykri::Analyze_StudyKRI_PredictBounds: No matching data found. Passing 'gsm.studykri::Analyze_StudyKRI_PredictBounds' as a string.
#>
#> ── Calling `gsm.studykri::ParseFunction`
#>
#> ── closure of length 1 saved as `lData$PredictBounds_Func`.
#>
#> ── Workflow Step 2 of 3: `purrr::map` ──
#>
#> ── Evaluating 5 parameter(s) for `purrr::map`
#> ✔ .x = Reporting_Join: Passing lData$Reporting_Join.
#> ✔ .f = PredictBounds_Func: Passing lData$PredictBounds_Func.
#> ✔ dfStudyRef = Mapped_StudyRef: Passing lData$Mapped_StudyRef.
#> ✔ nBootstrapReps = BootstrapReps: Passing lMeta$BootstrapReps.
#> ✔ nConfLevel = Threshold: Passing lMeta$Threshold.
#>
#> ── Calling `purrr::map`
#>
#> ── list of length 8 saved as `lData$Analysis_Bounds_Wide`.
#>
#> ── Workflow Step 3 of 3: `gsm.studykri::Transform_Long` ──
#>
#> ── Evaluating 1 parameter(s) for `gsm.studykri::Transform_Long`
#> ✔ lWide = Analysis_Bounds_Wide: Passing lData$Analysis_Bounds_Wide.
#>
#> ── Calling `gsm.studykri::Transform_Long`
#>
#> ── 5132x8 data.frame saved as `lData$Reporting_Bounds`.
#>
#> ── Returning results from final step: 5132x8 data.frame`. ──
#>
#> ── Completed `Reporting_Bounds` Workflow ───────────────────────────────────────
#>
#> ── Initializing `Reporting_BoundsRef` Workflow ─────────────────────────────────
#>
#> ── Checking data against spec
#> → All 2 data.frame(s) in the spec are present in the data: Reporting_Join, Mapped_StudyRef
#> → All specified columns in Mapped_StudyRef are in the expected format
#> → All 2 specified column(s) in the spec are present in the data: Mapped_StudyRef$study, Mapped_StudyRef$studyref
#>
#> ── Workflow Step 1 of 3: `gsm.studykri::ParseFunction` ──
#>
#> ── Evaluating 1 parameter(s) for `gsm.studykri::ParseFunction`
#> ℹ strFunction = gsm.studykri::Analyze_StudyKRI_PredictBoundsRef: No matching data found. Passing 'gsm.studykri::Analyze_StudyKRI_PredictBoundsRef' as a string.
#>
#> ── Calling `gsm.studykri::ParseFunction`
#>
#> ── closure of length 1 saved as `lData$PredictBoundsRef_Func`.
#>
#> ── Workflow Step 2 of 3: `purrr::map` ──
#>
#> ── Evaluating 6 parameter(s) for `purrr::map`
#> ✔ .x = Reporting_Join: Passing lData$Reporting_Join.
#> ✔ .f = PredictBoundsRef_Func: Passing lData$PredictBoundsRef_Func.
#> ✔ dfStudyRef = Mapped_StudyRef: Passing lData$Mapped_StudyRef.
#> ✔ nBootstrapReps = BootstrapReps: Passing lMeta$BootstrapReps.
#> ✔ nConfLevel = Threshold: Passing lMeta$Threshold.
#> ✔ bMixStudies = bMixStudies: Passing lMeta$bMixStudies.
#>
#> ── Calling `purrr::map`
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#> Calculated minimum group count: 146
#> Calculated minimum group count: 146
#> Calculated minimum group count: 69
#> Calculated minimum group count: 69
#>
#> ── list of length 8 saved as `lData$Analysis_BoundsRef_Wide`.
#>
#> ── Workflow Step 3 of 3: `gsm.studykri::Transform_Long` ──
#>
#> ── Evaluating 1 parameter(s) for `gsm.studykri::Transform_Long`
#> ✔ lWide = Analysis_BoundsRef_Wide: Passing lData$Analysis_BoundsRef_Wide.
#>
#> ── Calling `gsm.studykri::Transform_Long`
#>
#> ── 5102x11 data.frame saved as `lData$Reporting_BoundsRef`.
#>
#> ── Returning results from final step: 5102x11 data.frame`. ──
#>
#> ── Completed `Reporting_BoundsRef` Workflow ────────────────────────────────────

module_wf_gsm <- gsm.core::MakeWorkflowList(
  strNames = NULL,
  strPath = system.file("workflow/4_modules", package = "gsm.studykri"),
  strPackage = NULL
)

# we cannot set a dynamic link to the report path in the yaml files
report_path <- system.file("report", "Report_KRI.Rmd", package = "gsm.studykri")
n_steps <- length(module_wf_gsm$StudyKRI$steps)

module_wf_gsm$StudyKRI$steps[[n_steps]]$params$strInputPath <- report_path

lModule <- gsm.core::RunWorkflows(module_wf_gsm, lReporting)
#>
#> ── Running 1 Workflows ─────────────────────────────────────────────────────────
#>
#> ── Initializing `Module_StudyKRI` Workflow ─────────────────────────────────────
#>
#> ── No spec found in workflow. Proceeding without checking data.
#>
#> ── Workflow Step 1 of 6: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Reporting_Results: Passing lData$Reporting_Results.
#> ℹ strQuery = SELECT * FROM df
#> WHERE MetricID IN (
#>   'Analysis_kri0001',
#>   'Analysis_kri0002',
#>   'Analysis_kri0003',
#>   'Analysis_kri0004',
#>   'Analysis_kri0005',
#>   'Analysis_kri0007',
#>   'Analysis_kri0008',
#>   'Analysis_kri0011'
#> )
#> : No matching data found. Passing 'SELECT * FROM df
#> WHERE MetricID IN (
#>   'Analysis_kri0001',
#>   'Analysis_kri0002',
#>   'Analysis_kri0003',
#>   'Analysis_kri0004',
#>   'Analysis_kri0005',
#>   'Analysis_kri0007',
#>   'Analysis_kri0008',
#>   'Analysis_kri0011'
#> )
#> ' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 8902 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 8902x9 data.frame saved as `lData$ResultsLog`.
#>
#> ── Workflow Step 2 of 6: `gsm.core::RunQuery` ──
#>
#> ── Evaluating 2 parameter(s) for `gsm.core::RunQuery`
#> ✔ df = Reporting_Results: Passing lData$Reporting_Results.
#> ℹ strQuery = SELECT * FROM df
#> WHERE MetricID NOT IN (
#>   'Analysis_kri0001',
#>   'Analysis_kri0002',
#>   'Analysis_kri0003',
#>   'Analysis_kri0004',
#>   'Analysis_kri0005',
#>   'Analysis_kri0007',
#>   'Analysis_kri0011'
#> )
#> : No matching data found. Passing 'SELECT * FROM df
#> WHERE MetricID NOT IN (
#>   'Analysis_kri0001',
#>   'Analysis_kri0002',
#>   'Analysis_kri0003',
#>   'Analysis_kri0004',
#>   'Analysis_kri0005',
#>   'Analysis_kri0007',
#>   'Analysis_kri0011'
#> )
#> ' as a string.
#>
#> ── Calling `gsm.core::RunQuery`
#> Creating a new temporary DuckDB connection.
#> ✔ SQL Query complete: 7401 rows returned.
#> Disconnected from temporary DuckDB connection.
#>
#> ── 7401x9 data.frame saved as `lData$ResultsNorm`.
#>
#> ── Workflow Step 3 of 6: `gsm.studykri::MakeCharts_StudyKRI` ──
#>
#> ── Evaluating 6 parameter(s) for `gsm.studykri::MakeCharts_StudyKRI`
#> ✔ dfResults = ResultsLog: Passing lData$ResultsLog.
#> ✔ dfBounds = Reporting_Bounds: Passing lData$Reporting_Bounds.
#> ✔ dfBoundsRef = Reporting_BoundsRef: Passing lData$Reporting_BoundsRef.
#> ✔ dfMetrics = Reporting_Metrics: Passing lData$Reporting_Metrics.
#> ℹ nMaxMonth is of length 0: Parameter is a vector. Passing as is.
#> ℹ bLogY = TRUE: No matching data found. Passing 'TRUE' as a string.
#>
#> ── Calling `gsm.studykri::MakeCharts_StudyKRI`
#>
#> ── list of length 16 saved as `lData$lChartsLog`.
#>
#> ── Workflow Step 4 of 6: `gsm.studykri::MakeCharts_StudyKRI` ──
#>
#> ── Evaluating 5 parameter(s) for `gsm.studykri::MakeCharts_StudyKRI`
#> ✔ dfResults = ResultsNorm: Passing lData$ResultsNorm.
#> ✔ dfBounds = Reporting_Bounds: Passing lData$Reporting_Bounds.
#> ✔ dfBoundsRef = Reporting_BoundsRef: Passing lData$Reporting_BoundsRef.
#> ✔ dfMetrics = Reporting_Metrics: Passing lData$Reporting_Metrics.
#> ℹ nMaxMonth is of length 0: Parameter is a vector. Passing as is.
#>
#> ── Calling `gsm.studykri::MakeCharts_StudyKRI`
#>
#> ── list of length 14 saved as `lData$lChartsNorm`.
#>
#> ── Workflow Step 5 of 6: `BindLists` ──
#>
#> ── Evaluating 2 parameter(s) for `BindLists`
#> ✔ a = lChartsLog: Passing lData$lChartsLog.
#> ✔ b = lChartsNorm: Passing lData$lChartsNorm.
#>
#> ── Calling `BindLists`
#>
#> ── list of length 30 saved as `lData$lCharts`.
#>
#> ── Workflow Step 6 of 6: `gsm.studykri::Report_StudyKRI` ──
#>
#> ── Evaluating 6 parameter(s) for `gsm.studykri::Report_StudyKRI`
#> ✔ lCharts = lCharts: Passing lData$lCharts.
#> ✔ dfResults = Reporting_Results: Passing lData$Reporting_Results.
#> ✔ dfGroups = Reporting_Groups: Passing lData$Reporting_Groups.
#> ✔ dfMetrics = Reporting_Metrics: Passing lData$Reporting_Metrics.
#> ℹ strOutputFile = report_studykri.html: No matching data found. Passing 'report_studykri.html' as a string.
#> ℹ strInputPath = /home/runner/work/_temp/Library/gsm.studykri/report/Report_KRI.Rmd: No matching data found. Passing '/home/runner/work/_temp/Library/gsm.studykri/report/Report_KRI.Rmd' as a string.
#>
#> ── Calling `gsm.studykri::Report_StudyKRI`
#> processing file: Report_KRI.Rmd
#> output file: /tmp/RtmpUPTPVK/Report_KRI.knit.md
#> /opt/hostedtoolcache/pandoc/3.1.11/x64/pandoc +RTS -K512m -RTS /tmp/RtmpUPTPVK/Report_KRI.knit.md --to html4 --from markdown+autolink_bare_uris+tex_math_single_backslash --output /home/runner/work/gsm.studykri/gsm.studykri/vignettes/report_studykri_AA-1.html --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/pagebreak.lua --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/latex-div.lua --embed-resources --standalone --variable bs3=TRUE --section-divs --table-of-contents --toc-depth 3 --variable toc_float=1 --variable toc_selectors=h1,h2,h3 --variable toc_collapsed=1 --variable toc_smooth_scroll=1 --variable toc_print=1 --template /home/runner/work/_temp/Library/rmarkdown/rmd/h/default.html --no-highlight --variable highlightjs=1 --variable theme=flatly --mathjax --variable 'mathjax-url=https://mathjax.rstudio.com/latest/MathJax.js?config=TeX-AMS-MML_HTMLorMML' --include-in-header /tmp/RtmpUPTPVK/rmarkdown-str206726964acb.html --variable code_folding=hide --variable code_menu=1
#>
#> Output created: report_studykri_AA-1.html
#> processing file: Report_KRI.Rmd
#> output file: /tmp/RtmpUPTPVK/Report_KRI.knit.md
#> /opt/hostedtoolcache/pandoc/3.1.11/x64/pandoc +RTS -K512m -RTS /tmp/RtmpUPTPVK/Report_KRI.knit.md --to html4 --from markdown+autolink_bare_uris+tex_math_single_backslash --output /home/runner/work/gsm.studykri/gsm.studykri/vignettes/report_studykri_AA-2.html --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/pagebreak.lua --lua-filter /home/runner/work/_temp/Library/rmarkdown/rmarkdown/lua/latex-div.lua --embed-resources --standalone --variable bs3=TRUE --section-divs --table-of-contents --toc-depth 3 --variable toc_float=1 --variable toc_selectors=h1,h2,h3 --variable toc_collapsed=1 --variable toc_smooth_scroll=1 --variable toc_print=1 --template /home/runner/work/_temp/Library/rmarkdown/rmd/h/default.html --no-highlight --variable highlightjs=1 --variable theme=flatly --mathjax --variable 'mathjax-url=https://mathjax.rstudio.com/latest/MathJax.js?config=TeX-AMS-MML_HTMLorMML' --include-in-header /tmp/RtmpUPTPVK/rmarkdown-str20675d4c6047.html --variable code_folding=hide --variable code_menu=1
#>
#> Output created: report_studykri_AA-2.html
#>
#> ── character of length 2 saved as `lData$strReportPath`.
#>
#> ── Returning results from final step: character of length 2`. ──
#>
#> ── Completed `Module_StudyKRI` Workflow ────────────────────────────────────────